DEVELOPMENT
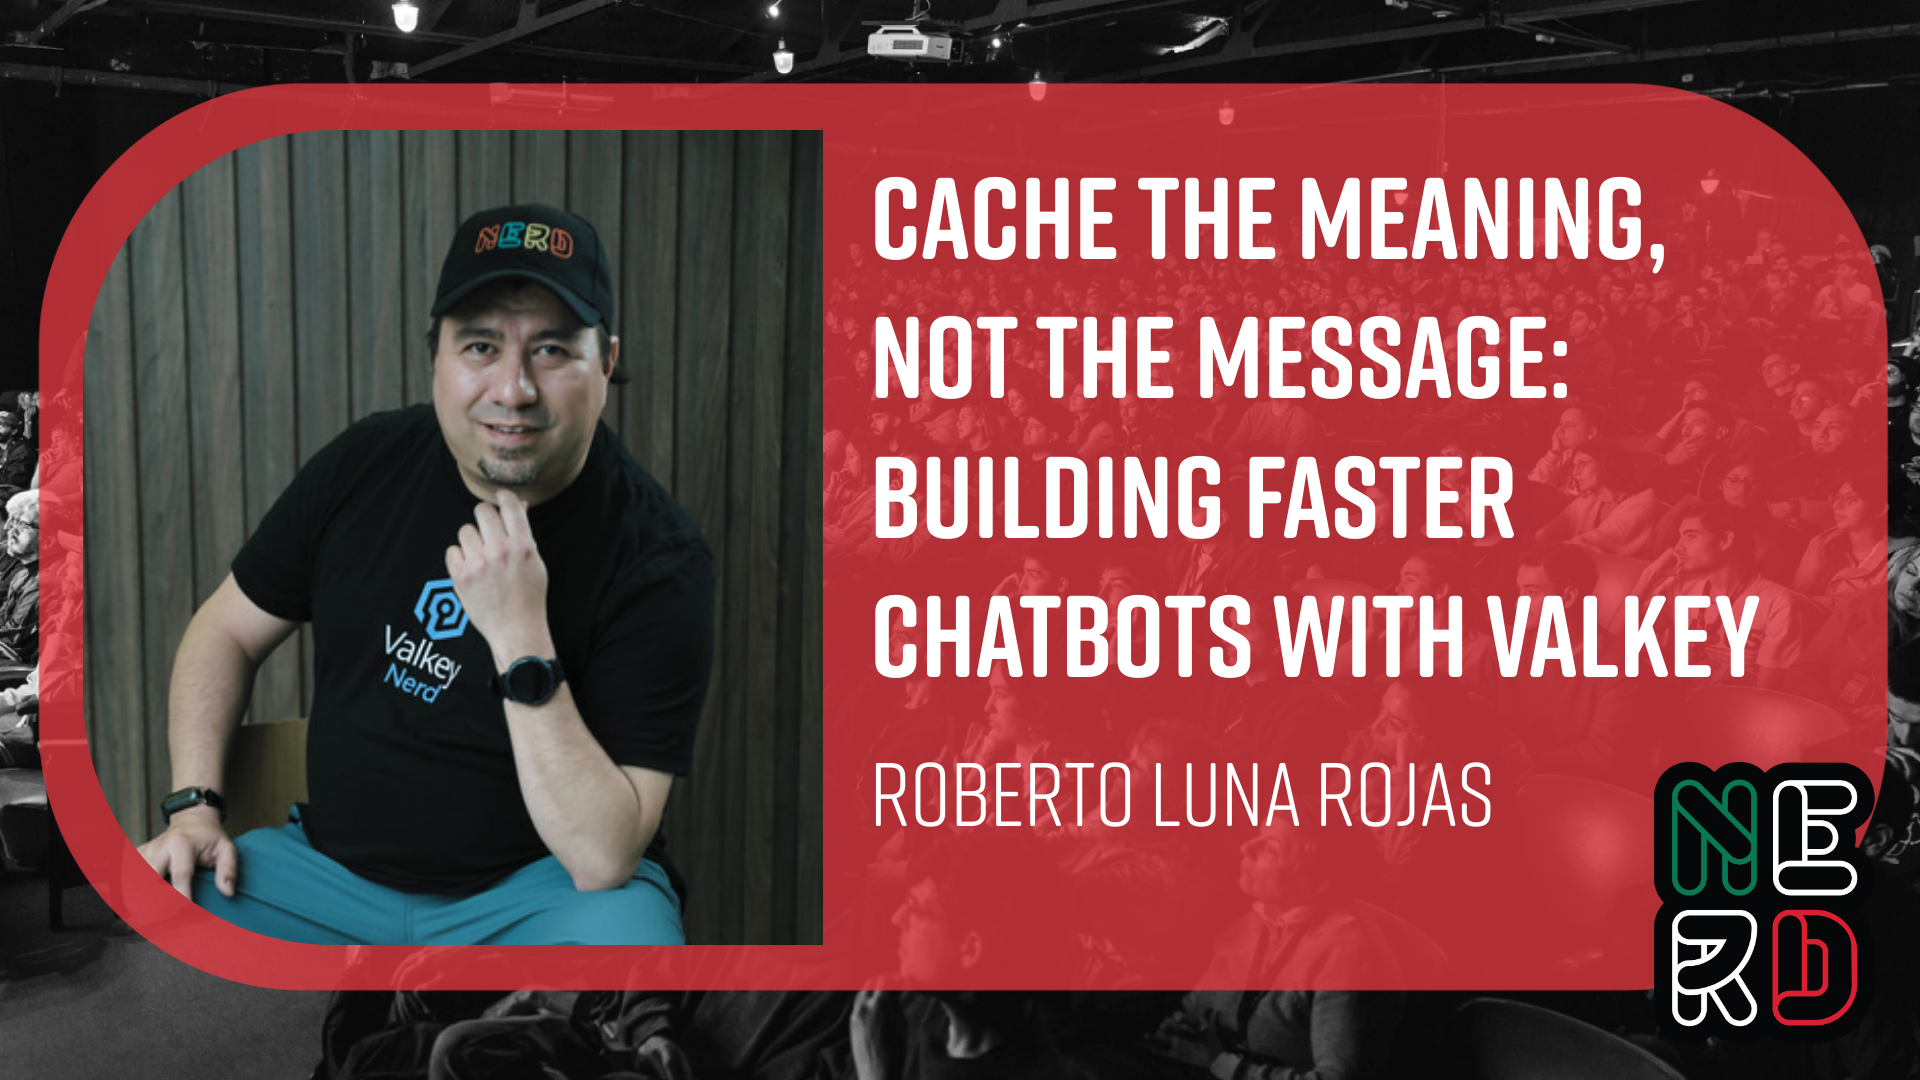
Cache the Meaning, Not the Message: Building Faster Chatbots with Valkey
“How do I return a product?” and “What’s the return process?” are different messages that often need the same answer. In a WhatsApp-style chatbot, repeatedly sending these questions to a large language model adds latency and cost. Exact-match caching misses the connection. Can we cache by meaning instead?
In this session, we’ll walk through a conversational application that uses Valkey with vector-search support as a semantic cache. We’ll turn incoming questions into embeddings, search for similar previously answered requests, and decide whether to reuse a response or invoke the model. A live demo will follow the request path from incoming message to reply, comparing behavior with and without caching.
The harder question is deciding when a similar question deserves a different answer. We’ll explore how conversation context, user-specific information, and changing business policies affect cache eligibility. You’ll see how similarity thresholds, expiration, and explicit invalidation help prevent incorrect reuse, and why personalized requests sometimes need to bypass the cache entirely.
You’ll leave with a reference architecture and an evaluation approach for measuring latency, model-call savings, and incorrect cache hits, so you can assess whether semantic caching improves your chatbot without compromising answer quality.
In this session, we’ll walk through a conversational application that uses Valkey with vector-search support as a semantic cache. We’ll turn incoming questions into embeddings, search for similar previously answered requests, and decide whether to reuse a response or invoke the model. A live demo will follow the request path from incoming message to reply, comparing behavior with and without caching.
The harder question is deciding when a similar question deserves a different answer. We’ll explore how conversation context, user-specific information, and changing business policies affect cache eligibility. You’ll see how similarity thresholds, expiration, and explicit invalidation help prevent incorrect reuse, and why personalized requests sometimes need to bypass the cache entirely.
You’ll leave with a reference architecture and an evaluation approach for measuring latency, model-call savings, and incorrect cache hits, so you can assess whether semantic caching improves your chatbot without compromising answer quality.
Regístrate para ver la charla de Roberto Luna Rojas
Regístrate gratisMás de DEVELOPMENT
10:10 - 11:00
David Cuartielles en Nerdearla
 David Cuartielles
Delega una tarea a GitHub Copilot: deja que el agente haga el trabajo
 Rogelio Oliva JARO
DEVELOPMENT
Escenario verde
Presenta

17:05 - 17:45
One Session, Multiple Surfaces: A Practical Copilot Workflow
 Humberto Tinoco
Goroutines baratas, cache misses caros: concurrencia en Go al nivel del silicio
 Juan Diego Latorre Ramirez